Priority-based scheduling automatically orders and assigns field service jobs by rules you set (SLA risk, safety, customer tier, revenue potential) instead of first-in-first-out queues or gut feel. Done properly, it protects contractual deadlines, lifts vehicle utilisation, and cuts the reactive firefighting that eats a dispatcher's day. The mechanics behind it, covered below, rest on structured priority tiers, SLA risk scoring, and an optimisation engine tuned through incremental testing.
TL;DR:
- Priority-based scheduling improves efficiency by adding 1 to 2 extra jobs per vehicle daily and reducing drive time by 20 to 30 percent.
- A four-tier model categorizes jobs into emergency, urgent, high, and normal, with automatic escalation and breach risk scoring cutting SLA breaches by up to 30 percent.
- Accurate, verified data on addresses, job details, technician skills, parts inventory, and customer tiers are critical before implementing the system.
- Weights assigned to objectives in the optimization engine must be balanced carefully to prevent inefficiencies, with incremental testing to avoid over-weighting priorities.
- Essential software features include SLA risk scoring with auto-escalation, live traffic updates, skills matching, inventory checks, and automatic customer ETA alerts.
Table of Contents
- How priority-based scheduling works in field-service software
- Priority framework and SLA tiers: a practical four-tier model
- Step-by-step implementation checklist for operations teams
- Configuring optimisation engines: weights, testing and common pitfalls
- Features and capabilities to require from software (procurement checklist)
- Lessons from a UK service business
- See how Curcle handles priority-based scheduling
- Sources
How priority-based scheduling works in field-service software
A scheduling engine can only make good decisions if it has good inputs. At minimum, it needs job priority (set by tier or business rule), the SLA window attached to that job, the skills and certifications required, parts availability, technician location, and the promised time window given to the customer. Feed those in and the system produces an ordered job queue, a technician assignment, an estimated time of arrival, and a re-routing recommendation when conditions shift.
A simple example: a gas leak call comes in tagged "emergency." The system checks which qualified engineers are nearest, confirms they're carrying the right parts, and slots the job ahead of a routine boiler service, even if that engineer was already midway through their route. The routine job doesn't vanish. It gets rescheduled against its own SLA window, and the customer gets an updated ETA automatically.
This only works if the engine keeps reading live conditions. A static morning plan is out of date by lunchtime once you account for traffic, cancellations, and jobs that overrun. Continuous re-optimisation and SLA-aware routing are what keep compliance and contractual windows intact as the day changes, rather than becoming aspirational once the first van hits a diversion.
What this typically delivers when it's running well:
- More jobs per vehicle: automated dispatch using live traffic, priority, skills, and parts data tends to add 1 to 2 extra completed jobs per vehicle per day.
- Less wasted driving: the same approach typically cuts drive time by 20 to 30 percent.
- Faster payback: for multi-vehicle operations, that combination often pays for itself in a relatively short payback period.
- Fewer surprise breaches: continuous re-optimisation catches drift before it becomes a missed compliance window.
Priority framework and SLA tiers: a practical four-tier model
Most field service operations don't need a bespoke priority system. A four-tier model covers the vast majority of job types and gives dispatchers a shared language for arguments they'd otherwise have every morning.
- Emergency — safety-critical faults: gas leaks, no heat in vulnerable households, lift failures, live electrical hazards. Target response typically measured in hours, sometimes minutes.
- Urgent — contractual SLA customers, breakdowns affecting business operations, jobs already past their promised window. Same-day or next-morning response.
- High — agreement customers, high-value commercial work, jobs with parts already booked. Response within 24 to 48 hours.
- Normal — routine servicing, planned maintenance, non-urgent call-outs. Response within the standard booking cycle.
Map your actual job types against these four bands before you touch any software settings, because the tiers only work if everyone agrees what sits where. Layer SLA breach risk scoring on top of the tiers and the system stops treating priority as static. A "normal" job that's been rescheduled twice and is now 18 hours from breaching its window should climb the queue automatically, without a dispatcher having to notice and intervene manually. Combining a four-tier structure with breach risk scoring and auto-escalation has been shown to cut SLA breaches by up to 30%.
Build in override rules from day one: a dispatcher should be able to manually bump a job for a documented reason (a director's request, a media-sensitive account, a genuine safety concern the system can't see), but that override should log a reason code. Otherwise your tiers erode within a month as "just this once" becomes the default.
Pro Tip: Don't let "customer shouted loudest" become an unofficial fifth tier. If overrides are happening weekly for the same account, that account probably belongs in a higher tier permanently, not exception-handled forever.
Step-by-step implementation checklist for operations teams
Rolling out priority-based scheduling fails more often on data quality than on software choice. Before you touch weightings or automation rules, get the foundations right.
Data prerequisites:
- Clean, verified addresses for every site, because bad address data quietly breaks route optimisation before it ever reaches the priority logic.
- Job templates that carry duration, skills, and parts requirements as standard fields, not free text.
- Accurate technician skills and certification records, kept current as people qualify or move roles.
- Parts inventory synced closely enough that the scheduler doesn't assign a job the engineer can't actually complete.
- Customer tier flags on every account, agreed with sales and account management, not just operations.
Intake changes: update your booking form or CRM intake so the person taking the call captures job type, urgency indicators, customer tier, and any promised window at the point of contact, not after the fact. Whoever answers the phone becomes the first link in the priority chain, so they need the fields in front of them and a clear rule for what counts as "emergency."
Pilot design: run priority-based scheduling on one team or one region for four to six weeks before going wider. Track SLA breaches, average drive time, and completed jobs per engineer per day against your baseline. Run the new logic in parallel with your existing process where you can, comparing suggested schedules before committing to them live.
Expect measurable movement fairly quickly: businesses combining live traffic, priority, and parts data into dispatch decisions typically see a noticeable increase in completed jobs per vehicle per day once the pilot settles in.
Dispatchers need training that reframes their job. They're no longer the ones deciding who goes where. They're managing exceptions the system flags, which is a different skill and needs to be taught as one.
Configuring optimisation engines: weights, testing and common pitfalls
The engine behind priority-based scheduling balances several competing objectives at once: priority tier, travel distance, skills match, and time windows. Weight one of these too heavily and you get a technically compliant schedule that's operationally useless.
The most common failure is over-weighting priority alone. Tell the system to "schedule high priority first" with no counterbalance and it will send your best engineer across the county for one urgent job while three routine jobs sit unassigned five minutes from where they started. Optimisation agents need consistent resource and requirement data, and objectives have to be balanced and tested incrementally, because over-weighting a single objective produces exactly that kind of inefficient, high-mileage schedule.
The tested approach:
- Start with similar weights across priority, travel, and skills, rather than assuming priority should dominate.
- Change one objective's weight at a time and observe the effect before adjusting another.
- Use review mode to inspect suggested schedules before they go live, not after.
- Run smaller, focused optimisation windows rather than one broad all-day pass; narrower runs tend to outperform broad ones.
Watch for these red flags during testing: engineers suddenly driving much further than before, jobs being rescheduled repeatedly within the same day, or the total count of completed jobs dropping even as "priority compliance" looks fine on paper. Any of those means a weight is out of balance, not that the model itself is wrong.
Pro Tip: Run scenario simulations against a single bad day from your history (the one with three emergencies and a broken van) before you trust any weighting change on a live schedule.
Features and capabilities to require from software (procurement checklist)
Strip away the marketing language and there's a short list of capabilities that actually determine whether priority-based scheduling works in practice. Use this when comparing platforms, regardless of what each vendor calls its own version.
Non-negotiable features:
- SLA risk scoring with automatic escalation, not just a static priority flag set once at intake.
- Live traffic awareness and real-time re-routing when conditions change mid-route.
- Skills and qualification matching that blocks assignment to unqualified engineers, rather than just suggesting it.
- Parts and inventory checks built into the assignment logic, so jobs aren't scheduled against stock that isn't there.
- Enforced time windows that respect customer-promised slots, not just internal SLA targets.
- Mobile ETA updates that reach the customer automatically when a job's position in the queue shifts.
When you get to a demo, ask the vendor to run a live scenario using your own job types and tiers, not their canned example. Ask what pilot support looks like and who handles data migration, since that's usually where projects stall. A mature system produces predictable, explainable results in a pilot: you should be able to ask why a job was scheduled where it was and get a straight answer, not a shrug about "the algorithm." Curcle's field service management platform is built around that principle, with the full feature set laid out on the Curcle features page.
Lessons from a UK service business
Priority-based scheduling changes what a dispatcher actually does day to day. Their job shifts from manually sequencing every job to managing the exceptions the system flags: the emergency that's just come in, the engineer stuck in traffic, the override request that needs a reason code. That's a harder job in some ways, not an easier one, but it's a better use of a skilled person's time.
The operational goals worth aiming for are consistent across the businesses this approach suits: fewer SLA breaches, less overtime spent firefighting a schedule that's already broken by 10am, and higher utilisation from the same fleet and headcount. Curcle was shaped by exactly this kind of operational reality, not designed in the abstract.
— Luke Herridge
See how Curcle handles priority-based scheduling
The platform brings SLA tracking, mobile engineer updates, and compliance support into the same system as job scheduling, so priority decisions aren't made in isolation from the certificates, assets, and customer records that actually determine urgency. That matters most for compliance-led trades, where a missed window isn't just a late job, it's a regulatory problem.
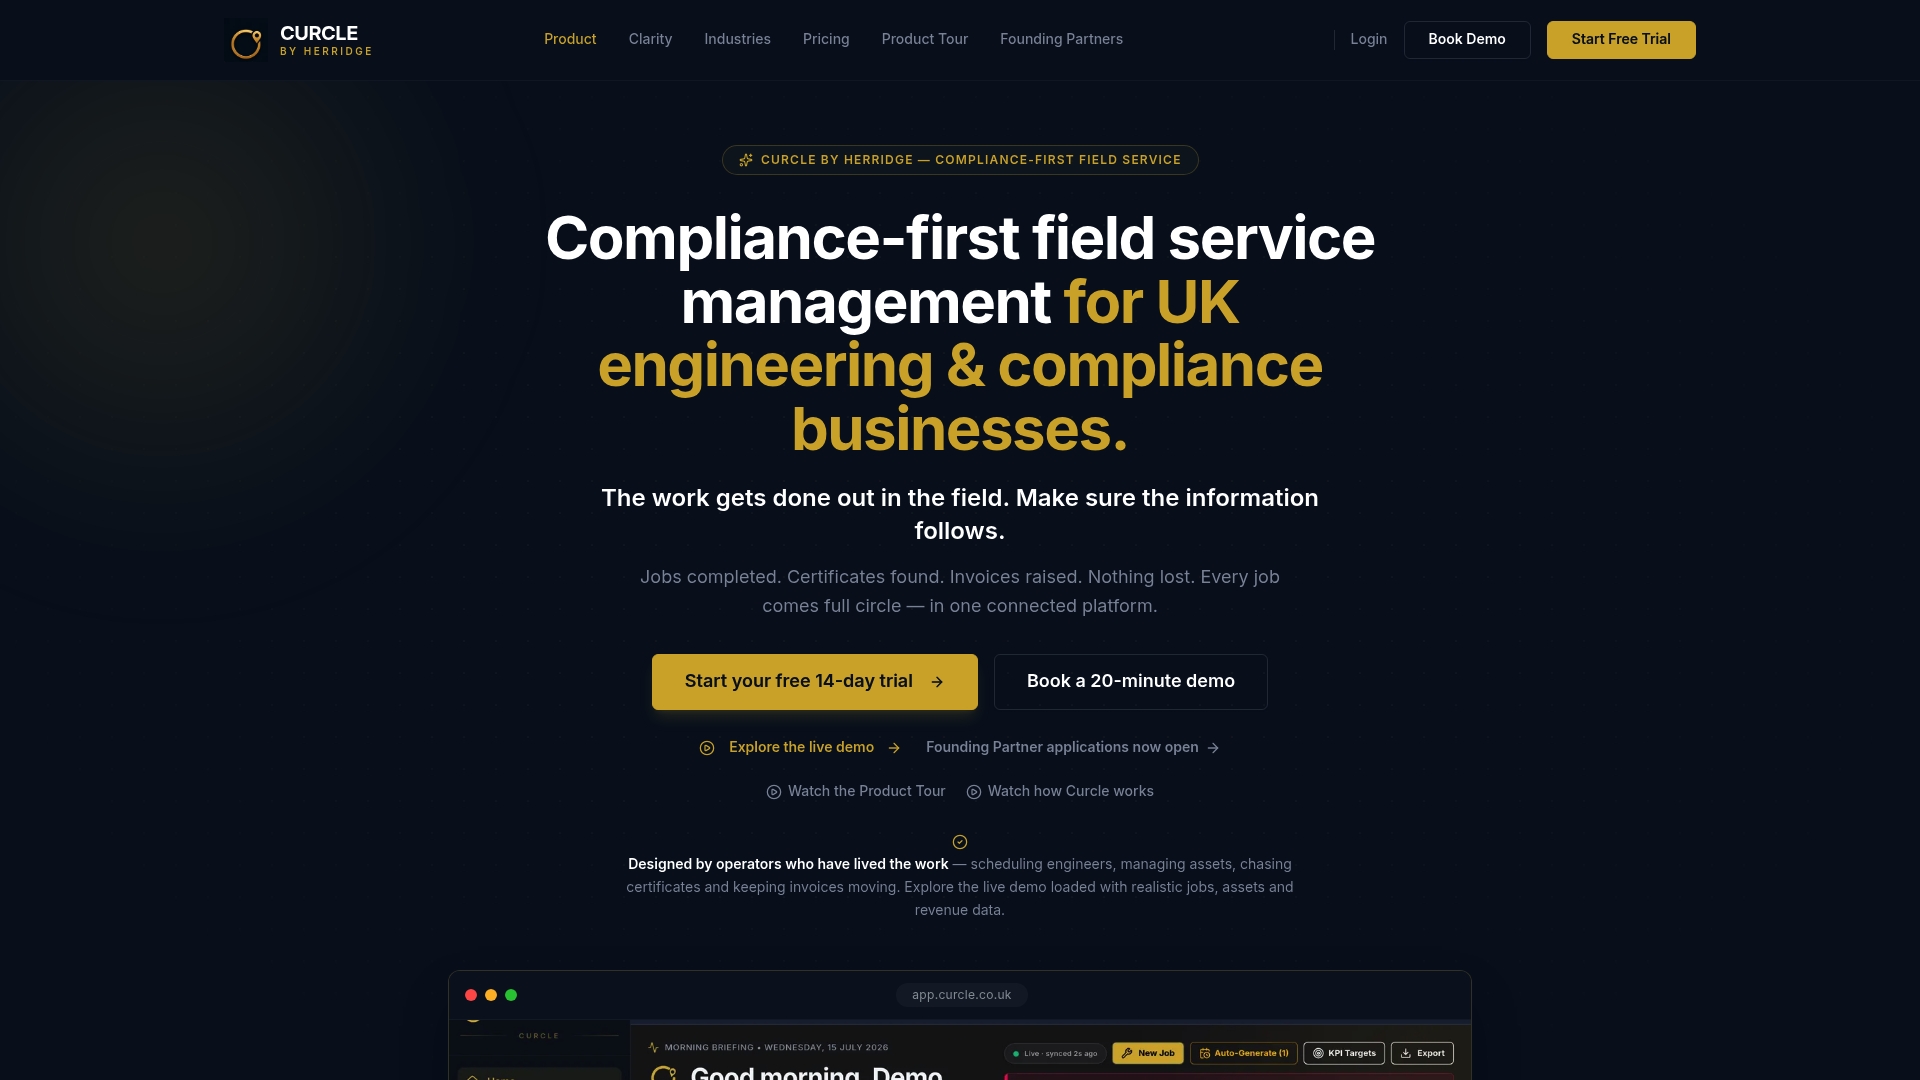
If the checklist above sounds like where your operation needs to get to, the fastest way to see whether it fits is to walk through it live rather than read another spec sheet. Curcle's product tour shows the scheduling and SLA logic in action before you commit to anything, and you can move straight to a quote request once you've seen it working against your own job types.
Sources
For the numbers behind the benefits claimed above, AnovaGrowth's breakdown of automated dispatch covers drive-time and throughput gains. Sparkco's guide to SLA risk scoring details the four-tier model and breach reduction figures. Microsoft's Dynamics 365 scheduling tuning guide is the clearest published reference on incremental weight testing. For the compliance angle, elogii's piece on missed SLA windows explains the cost of static planning in regulated work.
- Automated Dispatch for Service Businesses | AnovaGrowth
- Improve Scheduling Operations Agent results (preview) - Dynamics 365 Field Service | Microsoft Learn